When you build software with AI agents, tokens are your main budget.
Every token in your prompt slows down the model, costs money, and crowds the context window. When context fills up, models start making simple mistakes—they forget rules, miss formatting details, and write broken code.
Many developers try to fix this by adding more text to their system prompts. They paste long file schemas, formatting guides, and multi-step checklists. This is called prompt stuffing, and it usually makes the problem worse.
In this article, we show a better approach using three simple pieces:
- A local CLI tool that does the tedious formatting and validation.
- A short skill file that teaches the AI how to use the tool.
- The AI agent, which only loads instructions when it needs them.
We use this exact setup to manage content on this site (tahamertgokdemir.com), including publishing the article you are reading right now. Here is how it works.
1. The Problem: Why Big Prompts Fail
Imagine you have a website built with a static site generator—such as this site, which uses Hugo—and you want your AI agent to publish a new article.
To do that by hand, the AI must:
- Determine the correct file path (
content/article/<slug>.md). - Craft complex YAML frontmatter with exact fields: title, ISO-8601 timestamps with local timezone offsets, reading time estimates, categories, and tags.
- Verify that the slug matches your site’s permalink configuration so URLs do not 404.
- Format tags as a lowercase kebab-case array and ensure the category matches an approved taxonomy.
- Write valid markdown without breaking Hugo templates or HTML shortcodes.
If you explain all these rules in your system prompt:
- You waste tokens on every prompt. The model re-reads hundreds of lines of static rules on every single turn—even when you just ask it to fix a typo in CSS.
- The AI makes subtle mistakes. LLMs are great at reasoning, but they frequently bungle timezone offsets, miscalculate reading times, or produce invalid YAML spacing.
- The AI loses focus. When half of the context window is bureaucratic rules, the model has less attention left for writing clear, high-quality technical content.
2. The Solution: Three Simple Layers
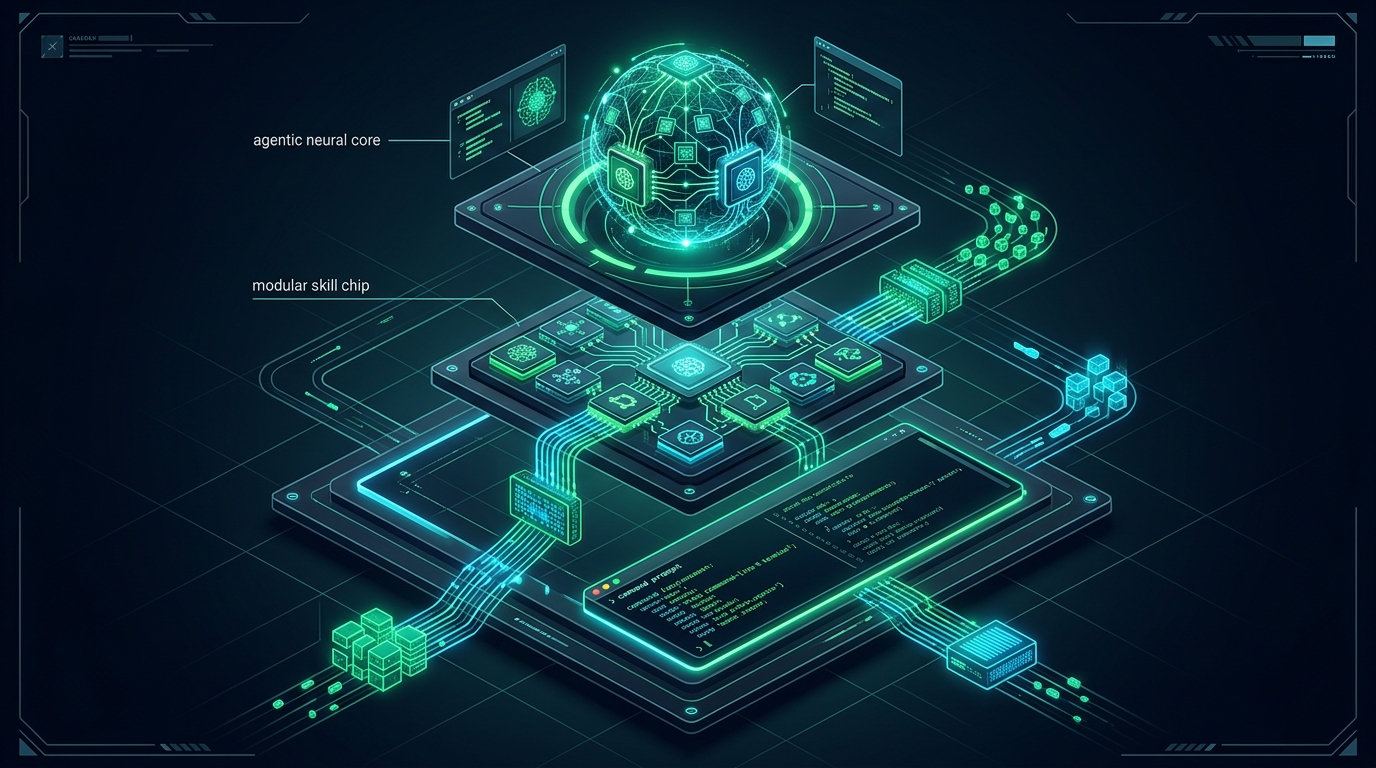
Instead of making the AI memorize file rules in its prompt context, we split the workflow into three layers:
  ┌───────────────────────────────────────────────────┐
  │                    AI Agent                       │
  │  Understands user intent and runs high-level tasks│
  └─────────────────────────┬─────────────────────────┘
                            │
               Loads skill only when needed
                            │
  ┌─────────────────────────▼─────────────────────────┐
  │                 Skill File (SKILL.md)             │
  │  Short guide with exact CLI flags and rules       │
  └─────────────────────────┬─────────────────────────┘
                            │
                     Runs the command
                            │
  ┌─────────────────────────▼─────────────────────────┐
  │                 Local CLI (tahablog)              │
  │  Creates files, sets YAML, and validates schemas  │
  └───────────────────────────────────────────────────┘
Here is how each layer works in practice.
Layer 1: The Local CLI Tool (./tahablog)
First, we built a standalone Bash utility called ./tahablog.
Instead of asking the AI to manually format YAML frontmatter and calculate date strings, the CLI handles all the mechanics directly:
- It creates the article markdown file in the correct directory.
- It inserts valid YAML frontmatter matching Hugo’s schema.
- It calculates the current timestamp with the exact local timezone offset (
+03:00). - It validates the category and slug.
- It returns clean JSON when passed
--json.
To scaffold a new article, the AI does not need to know any Hugo template rules. It runs a single command:
| |
The script runs in 15 milliseconds, generates the file, and prints JSON:
| |
Zero prompt tokens were spent explaining YAML formatting or timezone math.
Built by 4 AI Agents in 12 Minutes
A common hesitation with this approach is: “Writing a custom CLI with argument parsing, validation, error handling, and JSON output sounds like too much work just to save some prompt tokens.”
Here is the crucial part: we did not write this tool by hand.
We tasked a specialized team of 4 autonomous AI agents, running on Gemini 3.8 Flash, to build the entire CLI from scratch. The team completed the project in just 12 minutes, and it was fully functional and sufficient on the very first iteration:
- The Orchestrator: Coordinated the agent workflow, tracked project requirements, and managed smooth handoffs between roles.
- The Project Designer: Elaborated the complete CLI command set (
add,list,edit,publish,status), argument flags, validation constraints, and JSON schemas. - The Developer: Implemented the complete Bash codebase, handling flag parsing, ISO-8601 timezone offsets, atomic file writes, and clean JSON outputs.
- The Tester: Built an extensive automated test suite, stress-testing edge cases and verifying every command against the designer’s specification.
A single 12-minute run with a fast, cost-effective model produced a deterministic, permanent tool. That one-time investment now saves tens of thousands of tokens every time we write, edit, or publish content.
Layer 2: The Skill File (SKILL.md)
Next, the AI needs to know how to use the CLI. But we do not paste the entire manual into the base system prompt.
We use progressive disclosure:
- In the base system prompt, the AI only sees a 2-line summary in the skill registry:This takes fewer than 40 tokens.
1 2name: tahablog description: Use this tool to create, edit, list, and publish content in tahamertgokdemir.com. - The full operational guide stays on disk in a dedicated skill file (
SKILL.md). The AI only reads it when you ask it to work on articles or site content.
The skill file provides four straightforward operational rules:
- Never create article files by hand. Always scaffold using
./tahablog. - Pass flags non-interactively. Use
-n,-c,-s, and--publishedso commands run without stopping for interactive prompts. - Use
--jsonfor content inspection. Parse compact JSON instead of reading raw terminal dumps or running heavy shell commands. - Separate metadata from content. Let the CLI write the frontmatter; write your article body below it.
Layer 3: The AI in Action (How This Article Was Published)
Here is the exact sequence the AI followed to publish this article:
- Detected the task: You asked to write or update an article on token minimization.
- Loaded the skill on demand: The AI recognized a content task and read
SKILL.md. - Inspected existing articles: It ran
./tahablog article list --jsonto verify existing articles and categories (costing 74 tokens instead of 500+). - Scaffolded the file: It ran
./tahablog article addwith the title, slug, category, and estimated reading time. - Wrote the content: It opened the generated file and wrote the text directly below the frontmatter header.
- Configured the cover image: It generated the image asset and set
--thumbnailusing./tahablog article edit.
The entire process required zero guesswork, zero broken YAML, and minimal prompt overhead.
3. The Numbers: Before vs. After
Methodology: How We Measured Token Consumption
To verify that these savings are genuine, we benchmarked prompt payloads, tool executions, and multi-turn conversations using OpenAI’s tiktoken library with the cl100k_base encoding—the standard tokenizer used by modern frontier models (GPT-4, Claude, and Gemini class equivalents).
We compared two realistic workflows across identical content management tasks:
- Monolithic Prompting (Prompt Stuffing): The base system prompt embeds the full static site generator specifications, Hugo directory structures, and YAML schemas (1,936 tokens of static rules). Content inspection runs shell commands (
ls -laand file header dumps). Article scaffolding requires writing out full frontmatter manually, and typical formatting drift (invalid timezone formatting or YAML indentation) triggers one error-correction turn every 25 turns (~3,200 tokens). - Tool + Skill Architecture: The base system prompt contains only the lightweight skill registry entry (51 tokens). The comprehensive skill guide (3,634 tokens) is loaded once on demand only when a content task occurs. Content inspection uses structured CLI JSON output (
./tahablog article list --jsonat 74 tokens). Article scaffolding uses the single CLI command (87 tokens), and deterministic validation completely eliminates formatting retries.
Empirical Results
| Metric / Operation | Monolithic Prompting | Tool + Skill Setup | Difference |
|---|---|---|---|
| Base System Prompt Overhead | 1,936 tokens | 51 tokens | -97.4% |
| Content Discovery / Inspection | 547 tokens (ls -la + headers) | 74 tokens (./tahablog article list --json) | -86.5% |
| Article Scaffolding & Frontmatter | 219 tokens (manual YAML) | 87 tokens (CLI command + JSON) | -60.3% |
| Skill Guide (On-Demand) | Loaded on every turn | 3,634 tokens (loaded only when writing) | 0 tokens on other turns |
| Formatting & Timezone Errors | 10–20% drift (syntax, timezone, tags) | 0% (enforced by CLI validation) | Eliminated |
| Cumulative 25-turn Session | 54,226 tokens | 5,379 tokens | 48,847 tokens saved (-90.1%) |
| Cumulative 50-turn Session | 108,452 tokens | 7,124 tokens | 101,328 tokens saved (-93.4%) |
Why Cumulative Savings Compound
In agentic workflows, the model re-evaluates the system prompt and conversation history on every single turn.
In a 50-turn session, a 1,900-token prompt tax is paid 50 times—wasting over 95,000 tokens before the AI even reads your task. Add verbose directory listings and retry cycles, and the context window quickly degrades.
Under the Tool + Skill pattern, your base turns remain lightweight (~50 tokens). The heavy skill guide is pulled into context only during the turns where content is actually created, keeping your agent fast, cheap, and attentive.
4. Four Rules for Your Own Projects
You can apply this architecture to any codebase:
1. Put repetitive tasks into small scripts
If you find yourself explaining the same folder structure, file format, or build step to your AI more than twice, have an agent team write a dedicated script or CLI instead. You do not even have to build it manually—a quick sprint with fast models like Gemini Flash can generate reliable tools in minutes.
2. Make scripts take flags
Make sure your scripts run non-interactively. Add flags for required inputs (like -n, -c, or --published) and avoid interactive prompts so the agent never hangs.
3. Output clean JSON
Add a --json flag to your scripts. AIs parse JSON faster, cheaper, and more reliably than raw terminal tables or unstructured text dumps.
4. Load instructions on demand (Progressive Disclosure)
Do not pack every operational rule into your main system prompt or base configuration. Keep your main prompt short, and store detailed runbooks in modular skill files that the AI loads only when needed.
Summary
Better AI coding is not about writing longer prompts. It is about giving the AI simple tools and clear, short instructions.
When you let a local tool handle the administrative work, you save tens of thousands of tokens and keep the AI’s full attention on what matters: solving hard problems and writing good software.
This article was scaffolded using ./tahablog and written following the Tool + Skill pattern.